




The best way to improve AI safety? Challenge it.
Ethical hackers stress-test AI systems to uncover unsafe behaviors before attackers or users do.
Find vulnerabilities, sensitive data exposure, prompt injection, unsafe outputs, poisoned retrieval, tool abuse, and harmful AI behavior before they affect customers or your business.
Turn higher volume into validated signal through managed triage, clear scope design and human-in-the-loop review.
Always-on crowdsourced security testing: Don't wait for a point-in-time audit. Our Bug Bounty model provides 24/7 testing that evolves as quickly as your AI-driven attack surface.
Drive more impact from your existing security budget: Intigriti’s flexible bug bounty model lets you expand testing when you need it.


A company can buy a single AI security product. Or they can work with thousands of hackers on Intigriti, each running their own AI stack, their own models, their own prompts, their own creative angle. One vendor's AI versus thousands of hackers amplified by AI.
Stijn Jans
CEO
Responsible AI needs adversarial thinking

Sensitive data exposure: Test whether users can extract confidential data, system prompts, privileged context, internal instructions, or data from connected systems.

Prompt injection and model manipulation: Challenge prompts, instructions, guardrails, and model behavior to uncover unsafe or unintended responses.

RAG and retrieval abuse: Identify whether poisoned, untrusted, or over-permissioned documents can influence outputs, decisions, or actions.

Agent, API, and tool abuse: Test APIs, plugins, tool calls, and downstream systems to ensure your AI cannot be used as a backdoor to access internal networks, execute unauthorized commands, or alter workflows.

Harmful or misleading outputs: Defend against model manipulation that could result in harmful, biased, or incorrect content that damages customer trust or corporate credibility.
Chained security and safety failures: Find scenarios where one weakness enables another, for example, a safety bypass that enables a tool call or a leaked prompt that supports data access.
A tailored program, not a generic AI checklist

Custom AI scope
We help map the AI systems, prompts, tools, agents, RAG sources, guardrails, and downstream workflows that need to be tested.

Worst-case outcome mapping
We work with your team to define what really matters: customer harm, data exposure, regulatory impact, brand damage, unsafe automation, or misuse of connected tools.

Hybrid severity model
We combine CVSS-based scoring for AI security findings with a custom safety severity table for AI safety findings, plus clear logic for chained findings.

Specialist researcher engagement
We help engage researchers with relevant experience across prompt injection, agent abuse, RAG attacks, safeguard bypasses, output handling and AI-assisted vulnerability discovery.

AI-fluent triage
Our triage process is built to validate evidence, reduce noise and keep humans responsible for judgment-heavy decisions.

Continuous calibration
AI systems change quickly. Your testing program should evolve as models, prompts, tools, retrieval sources and product behaviors change.


Talk to an AI security expert
Tell us what you are building. We’ll help map your AI attack surface, identify the risks that matter, and recommend the right testing program.
How it works
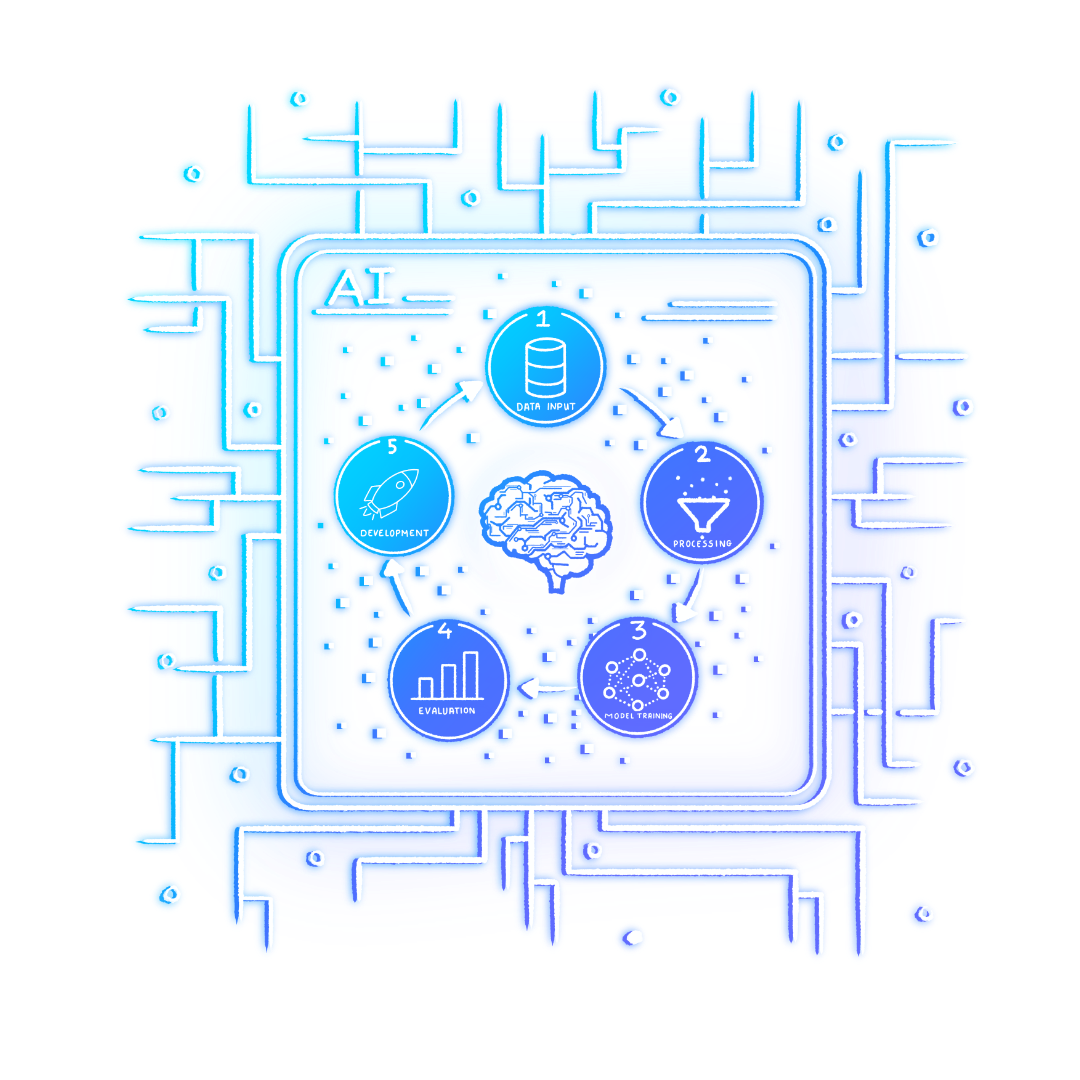
Whether you are running Bug Bounty, a VDP, or PTaaS, here is how we design every AI security and safety program we run.

Scope your AI surface
We work with your security, engineering, and product teams to understand how AI is used, what it can access and where risk could emerge.

Define what matters
Together, we map your worst-case outcomes and define the safety, security, and business risks your program should prioritize.

Design the right program
We shape the scope, evidence requirements, reward model, researcher access, safety categories and reporting approach around your goals.

Launch, learn and recalibrate
We help engage the right researchers, validate findings through managed triage and refine the program as your AI systems evolve.